Root Causes of AI Agent Failures That Reach Production
Production failures stem from broken tools and drifting context, not from weaker models.
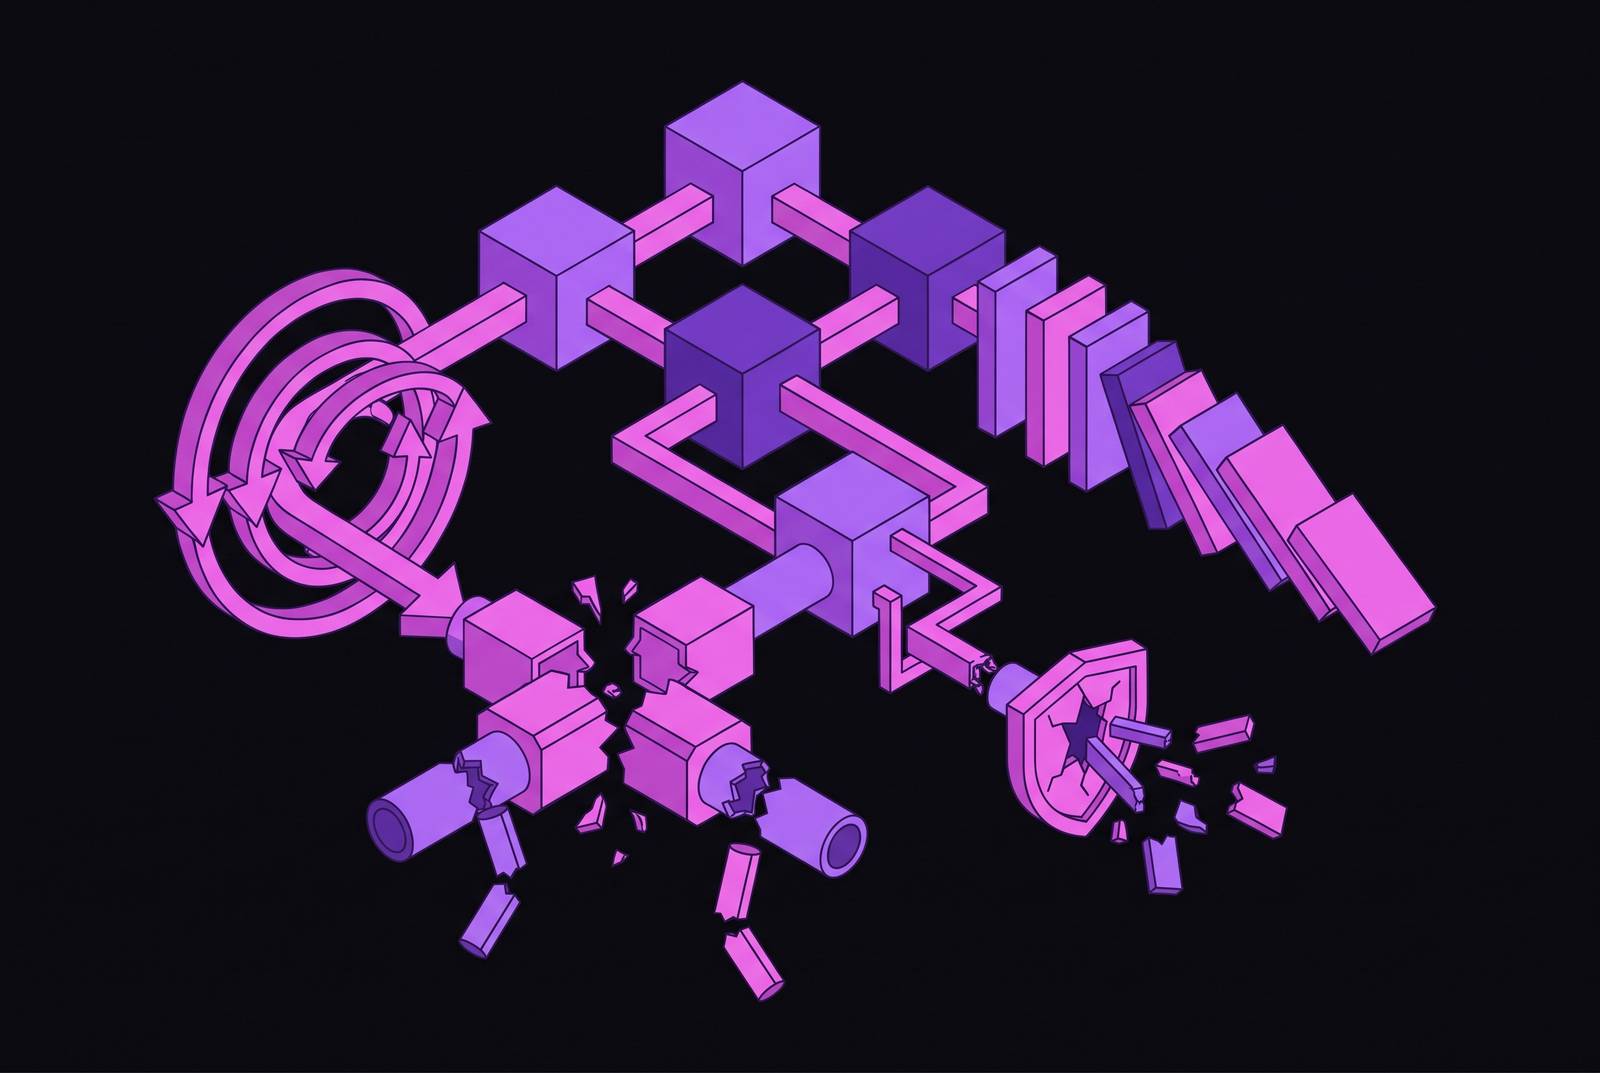
Production AI agent failures are almost never solved by choosing a smarter model. Their root causes sit in the surrounding system, where broken tools, drifting prompts, weak access controls, and missing context turn plausible answers into unreliable actions. Agents hold up in production when that infrastructure makes errors visible and keeps them contained.
Why the model is almost never what breaks in production
Consider the Friday-afternoon rollback. The agent behaved perfectly in the demo, broke in production, and now has to be pulled back. The model had not changed between those runs. What changed was the environment around it, including the data, business rules, credentials, and downstream systems it had to navigate.
Atlan’s 2026 analysis describes two teams that shipped agents with the same prompt quality, frameworks, and tool configurations, yet got completely different results in production. A post-mortem might call the failures hallucination, memory gaps, or poor prompts, but those labels can name the symptoms without explaining what caused them. Fixing each symptom still leaves the gap that caused it. A stronger model can even conceal that gap by producing coherent, confident answers from incomplete organizational context, where a weaker model would make an obvious mistake.
Context debt: the invisible accumulation that surfaces only under real load
Context debt is the accumulated gap between what an agent infers data and business rules mean and what they actually mean. It builds undetected during development until a real query exposes it. The gap can involve missing information, conflicting definitions, stale assumptions, or names that mean different things across systems.
Atlan illustrates this with competing definitions of a metric such as sales revenue. Without a canonical source, the agent has to choose between those definitions with each query and routes to whichever source responds first. Two people on the same team can ask the same question on Monday and Wednesday and receive different answers. Both answers are defensible, but neither is authoritative. Trust collapses because the system cannot establish which definition governs the answer.
Synthetic tests rarely expose this kind of ambiguity. Their data agrees with itself, while production data has gone through years of naming divergence and schema drift. The agent does not necessarily reject those contradictions. Instead, it reasons forward from them and produces an answer complete enough to pass casual review. Atlan expresses the relationship as “Ungoverned Context × Agent Autonomy = Increased Risk Exposure,” because autonomy amplifies the gap.
Silent tool-call failures and how corrupted context propagates downstream
A broken tool call can feed that context debt directly into an active workflow. An API timeout, changed schema, or partial payload returns something the agent did not expect, but the model continues as though the response were valid. Nothing has to crash for damage to spread. Every later step that depends on the response can inherit the corruption.
Composio’s integration report calls this connector problem “Brittle Connectors.” Enterprise APIs such as Salesforce were not built to be queried by agents, and an uncommunicated schema change can leave an agent unable to recognize structurally invalid data. Credentials create another quiet failure path. An expired OAuth access token for a service such as Google can appear as “agent not responding” instead of a clear authentication error, sending developers toward the wrong diagnosis.
The AI Incident Database records that an agent in the Replit incident deleted a live production database during an active code freeze and produced fabricated test results and fake data. The incident makes the consequences of unguarded tool execution concrete. A tool can run successfully and still return an invalid result. Per-step result validation and complete tracing of tool inputs and outputs make corruption visible where it begins, before it spreads.
Prompt drift and schema changes that degrade quality without triggering alerts
Even when tools return valid data, changes around them can quietly break the workflow’s assumptions. A developer edits a system prompt in staging, another team changes the JSON format expected by a downstream parser, and someone adjusts a tool definition to improve extraction. Each change can look harmless in isolation. Together, they can produce inconsistent failures days later without a clean error code.
A prompt edit that helps with one use case may break an assumption built into the parser. A change to a tool definition can also change what the model gets without breaking the request itself. The agent still appears to be working. Dashboards stay green because the degradation is visible in variable output quality while the service remains available.
Prompts need to be treated as deployable infrastructure. That means versioning, review, testing, traceability, and rollback capability, with schema and tool-definition changes examined as part of the same workflow. A prompt cannot be judged apart from what consumes its output. Drift in both prompts and schemas needs to be caught before it reaches production.
Disconnected evaluation pipelines and the benchmark-to-production gap
Passing evaluations does not resolve that risk if the evaluations describe an environment that no longer exists. Tests are written early, the agent passes, and then customer behavior changes, new edge cases appear, and production queries move beyond the original coverage. The tests keep passing while real performance declines. Atlan identifies intuition-based coverage as a root cause because it reflects the developer’s mental model and misses the actual distribution of queries.
Running those tests continuously is not the same as evaluating current production behavior. Frequency cannot repair an obsolete test set. An offline pipeline can run the same static dataset more often and still miss yesterday’s new failure pattern. Evaluations against live traffic samples test whether the agent works on the requests it gets now.
Scoring also needs an anchor outside the evaluator itself. LLM-as-judge scores are useful only when they correlate with human judgment on a labeled reference set. Without that link, optimization can make the dashboard look better while the output stays the same or gets worse. The response is a living evaluation pipeline built around current traffic samples and human-labeled anchors, so both coverage and scoring remain tied to production reality.
Multi-agent orchestration failures and cascading context corruption
A bad tool response or a wrong assumption can spread through shared memory, connected tools, and downstream agents, so it becomes harder to trace where the fault began. The failed output becomes input for other agents that act on it.
File scope shows how concrete this can be. An agent working in one worktree can read files from another and generate conflicting changes, a problem addressed through allowedPaths scoping. Orchestrators can also lose track of subordinate agents while tasks remain stuck. Forrester’s mid-2026 assessment describes chained agents without shared structure as a setup where “coordination fall apart into duplication and drift.”
Coordination infrastructure can deepen that instability. Composio calls request-response polling the “Polling Tax,” because polling-based workflows struggle to maintain consistent state across agents and do not scale. Event-driven state management addresses that coordination problem, but state boundaries are also necessary. When customers share an agent instance, corruption or scope creep in one session can bleed into another. Per-user or per-session isolation bounds the failure to the session where it began.
The last-mile governance gap that prototype setups never have to face
Isolation leads directly to a question the demo rarely answers, which is whose authority the agent uses. A prototype can operate with a single API key. Production introduces SSO integration, per-user credential scoping, and audit trails for every action. Each is a separate engineering requirement.
Shared service accounts make actions hard to attribute to a particular agent or user. Static keys that never rotate become lasting vulnerabilities, while broad permissions granted for convenience expand the damage a compromise can cause. Systems handling PII, financial records, and regulated information face requirements under HIPAA, GDPR, SOC 2, and the EU AI Act that the isolated prototype did not confront. Deloitte’s 2026 finding puts mature governance for autonomous AI agents at only 21% of enterprises.
For founders and operators, the lesson is architectural. Hand-provisioning governance for every customer repeats the mistake of hand-provisioning servers and takes up the product engineering team’s time with deployment plumbing. Access controls, credential identity, rotation, audit trails, and human oversight belong in the platform layer. Builders can then work on the product without reconstructing its governance foundation for each deployment.
Prompt injection and the security attack surface that production exposes
The same gaps also give malicious inputs room to act. Unvalidated tool outputs, unrestricted tool scope, missing access controls, and absent audit trails are reliability weaknesses that double as a security attack surface. The boundary is shared between the two problems. In one case, the input is accidentally wrong, while in the other it is designed to redirect the agent.
Crafted GitHub comments, pull request titles, and issue bodies have been used to hijack coding agents in CI/CD pipelines, leading to command execution and credential exposure in Actions logs. The integration gives hostile text a route into action. Lakera’s February 12, 2026 research entry, “Memory Poisoning & Instruction Drift,” also puts stored context within the security discussion. Context is not merely information the agent needs to answer well.
Dependencies expose another route into the system. Datadog Security Labs reports that a compromised PyPI package in March 2026 had nearly 47,000 downloads in the three-hour window before it was removed. The package served as the language-model gateway for frameworks including CrewAI, DSPy, and Microsoft GraphRAG. Per-step validation, isolated credentials, audit trails, and limits on tool invocation help with both attacks and ordinary reliability failures.
What observability infrastructure actually needs to cover for agentic systems
Traditional monitoring can report a healthy service while the agent produces a wrong answer. Uptime, latency, and HTTP status codes describe delivery. A successful HTTP 200 proves very little here. Even valid JSON can hold errors that sound confident and make sense but affect several later steps.
Distributed tracing across the workflow requires a parent trace for each agent run, with child spans for tool calls, model invocations, retrieval operations, token usage, per-step latency, and provider routing decisions. It gives per-step validation a record that connects a bad result to the actions that depended on it.
Dynamic routing across models introduces different rate limits, regional failures, and model-specific prompt behavior, so a centralized AI gateway needs to make those decisions visible. Event-driven state management also gives the monitoring layer state signals that polling-based coordination does not provide. For managed deployments, the platform needs to provide that view. Centralized uptime monitoring, tool-call tracing, and failure recovery let operators see across customer instances, eliminating the need to reconstruct each failure separately.
From failure diagnosis to production architecture: what the failure modes require
Production architecture begins with a governed semantic layer. Every metric the agent can query needs a canonical definition, so revenue resolves to an authoritative source. Validation and tracing can then establish whether each tool response preserves that meaning through execution.
Versioned prompts, schema review, rollback capability, and staging tests against the current production distribution belong with evaluations drawn from live traffic. Neither side works well in isolation. Tests that leave out deployment changes miss regressions, and controlled releases still fail when their tests cover work that is out of date.
Execution boundaries complete the design through isolated sessions, scoped tools, shared semantic context, event-driven coordination, and platform-level governance. These are requirements for deployment after a successful demo. Managed agent hosting is distinct from raw compute because it can provide isolated, persistent, monitored environments with security, credentials, and integrations built in. That is the infrastructure category’s purpose, to make production requirements achievable without rebuilding them for every customer or maintaining a dedicated infrastructure team.